Showing posts with label Downtime Reports. Show all posts

Thursday, May 10, 2012

Uptime Report for my Live OakLeaf Systems Azure Table Services Sample Project: April 2012

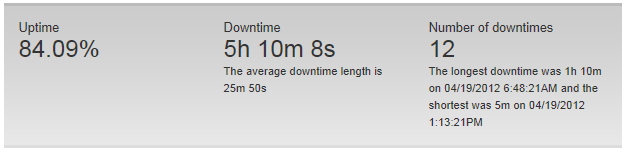
My live OakLeaf Systems Azure Table Services Sample Project demo runs two small Windows Azure Web role instances from Microsoft’s South Central US (San Antonio, TX) data center. I didn’t receive (or misplaced) the usual Pingdom Monthly Report for April, so here’s the detailed uptime report from Pingdom.com for April 2012:

image

This is the first case of monthly uptime below the 99.95% minimum Windows Azure Compute Service Level Agreement (SLA) guarantee since upgrading the sample app to two instances. My Flurry of Outages on 4/19/2012 for my Windows Azure Tables Demo in the South Central US Data Center post updated 4/30/2012 provides details about the outage on 4/19/2012 and its root cause analysis.


Following is detailed Pingdom response time data for the month of March 2012:

image


This is the eleventh uptime report for the two-Web role version of the sample project. Reports will continue on a monthly basis.

Month Year Uptime Downtime Outages Response Time
April 2012 99.28% 05:10:08 12 795 ms
March 2012 99.96% 00:20:00 1 767 ms
February 2012 99.92% 00:35:00 2 729 ms
January 2012 100.00% 00:00:00 0 773 ms
December 2011 100.00% 00:00:00 0 765 ms
November 2011 99.99% 00:05:00 1 708 ms
October 2011 99.99% 00:04:59 1 720 ms
September 2011 99.99% 00:05:00 1 743 ms
August 2011 99.98% 00:09:57 2 687 ms
July 2011 100.00% 00:00:00 0 643 ms
June 2011 100.00% 00:00:00 0 696 ms

The Azure Table Services Sample Project

See my Republished My Live Azure Table Storage Paging Demo App with Two Small Instances and Connect, RDP post of 5/9/2011 for more details of the Windows Azure test harness instance.

image_thumb2_thumb_thumb1_thumb_thum[1]

image_thumb7I believe this project is the oldest continuously running Windows Azure application. I first deployed it in November 2008 when I was writing Cloud Computing with the Windows Azure Platform for Wiley/WROX, which was the first book published about Windows Azure.

The application runs the default set of Windows Azure Diagnostics. About 5 GB of Event Counter data provides the source data for my Generating Big Data for Use with SQL Azure Federations and Apache Hadoop on Windows Azure Clusters post of 1/8/2012.

For more details about the Table Services Sample project or to download its source code, visit its Microsoft Pinpoint entry. Following are Pinpoint listings for three other related OakLeaf sample projects, two of which are live in the South Central US data center:


Monday, April 30, 2012

Flurry of Outages on 4/19/2012 for my Windows Azure Tables Demo in the South Central US Data Center

•• Updated 4/30/2012 with root cause analysis (RCA) details.

• Updated 4/26/2012 with details of similar outage in the North Central U.S. data center on 4/25/2012 and another South Central U.S. data center outage on the same date. See items marked • near the end of this post.

My OakLeaf Systems Azure Table Services Sample Project (Tools v1.4 with Azure Storage Analytics) demo application, which runs on two Windows Azure compute instances in Microsoft’s South Central US (San Antonio) data center incurred an extraordinary number of compute outages on 4/19/2012. Following is the Pingdom report for that date:

imageimage

image

The Mon.itor.us monitoring service showed similar downtime.

This application, which I believe is the longest (almost) continuously running Azure application in existence, usually runs within Microsoft’s Compute Service Level Agreement for Windows Azure: “Internet facing roles will have external connectivity at least 99.95% of the time.”

The following table from my Uptime Report for my Live OakLeaf Systems Azure Table Services Sample Project: March 2012 post of 4/3/2012 lists outage and response time from Pingdom for the last 10 months:

image

The Windows Azure Service Dashboard reported Service Management Degradation in the Status History but not problems with existing hosted services:

image

[RESOLVED] Partial Service Management Degradation

19-Apr-12
11:11 PM UTC We are experiencing a partial service management degradation in the South Central US sub region. At this time some customers may experience failed service management operations in this sub region. Existing hosted services are not affected and deployed applications will continue to run. Storage accounts in this sub region are not affected either. We are actively investigating this issue and working to resolve it as soon as possible. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.

20-Apr-12
12:11 AM UTC We are still troubleshooting this issue and capturing all the data that will allow us to resolve it. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.

1:11 AM UTC The incident has been mitigated for new hosted services that will be deployed in the South Central US sub region. Customers with hosted services already deployed in this sub region may still experience service management operations failures or timeouts. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.

1:47 AM UTC The repair steps have been executed and successfully validated. Full service management functionality has been restored in the affected cluster in the South Central US sub-region. We apologize for any inconvenience this has caused our customers.

However, Windows Azure Worldwide Service Management did not report problems:

image

I have requested a Root Cause Analysis from the Operations Team and will update this post when I receive a reply. See below.

• Mon.itor.us reported that my OakLeaf Systems Azure Table Services Sample Project (Tools v1.4 with Azure Storage Analytics) demo suffered another 30 minute outage on 4/25/2012 starting at 8:10 PM.

•• Avkash Chauhan, a Microsoft Sr. Escalation Engineer and frequent Windows Azure and Hadoop on Azure blogger, reported the root cause of the outage as follows:

At approximately 6:45 AM on April 19th, 2012 two network switches failed simultaneously in the South Central US sub region. One role instance in your ‘oakleaf’ compute deployment was behind each of the affected switches. While the Windows Azure environment is segmented into fault domains to protect from hardware failures, in rare instances, simultaneous faults may occur.

As this was a silent and intermittent failure, detection mechanisms did not alert our engineering teams of the issue. We are taking action to correct this at platform and network layers to ensure efficient response to such issues in the future. Further, we will be building additional intelligence into the platform to handle such failures in an automated fashion.

We apologize for any inconvenience this issue may have caused.

Thank you,

The Windows Azure team


• The Windows Azure Operations Team reported [Windows Azure Compute] [North Central US] [Yellow] Windows Azure Service Management Degradation on 4/24/2012:

Apr 24 2012 10:00PM We are experiencing a partial service management degradation with Windows Azure Compute in the North Central US sub region. At this time some customers may experience errors while deploying new hosted services. There is no impact to any other service management operations. Existing hosted services are not affected and deployed applications will continue to run. Storage accounts in this region are not affected either. We are actively investigating this issue and working to resolve it as soon as possible. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.

Apr 24 2012 11:30PM We are still troubleshooting this issue, and capturing all the data that will allow us to resolve it. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.

Apr 25 2012 1:00AM We are working on the repair steps in order to address the issue. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.

Apr 25 2012 1:40AM The repair steps have been executed successfully, the partial service management degradation has been addressed and the resolution verified. We apologize for any inconvenience this caused our customers.

Following is a snapshot of the Windows Azure Service Dashboard details pane on 4/25/2012 at 9:00 AM PDT:

image

The preceding report was similar to the one I reported for the South Central US data center above. That problem affected hosted services (including my Windows Azure tables demo app). I also encountered problems creating new Hadoop clusters on 4/24/2012. Apache Hadoop on Windows Azure runs in the North Central US (Chicago) data center, so I assume services hosted there were affected, too.

• Update 4/26/2012: Microsoft’s Brad Sarsfield reported in a reply to my Can't Create a New Hadoop Cluster thread of 4/25/2012 on the HadoopOnAzureCTP Yahoo! Group:

Things should be back to normal now. Sorry for the hiccup. We experienced a few hours of deployment unreliability on Azure.

Update 4/25/2012 9:30 AM PDT: The problem continues with this notice:

Apr 25 2012 3:12PM We are experiencing a partial service management degradation with Windows Azure Compute in the North Central US sub region. At this time some customers may experience errors while carrying out service management operations on existing hosted services. There is no impact to creation of new hosted services. Deployed applications will continue to run. Storage accounts in this region are not affected either. We are actively investigating this issue and working to resolve it as soon as possible. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.


Tuesday, April 03, 2012

Uptime Report for my Live OakLeaf Systems Azure Table Services Sample Project: March 2012

My live OakLeaf Systems Azure Table Services Sample Project demo runs two small Windows Azure Web role instances from Microsoft’s South Central US (San Antonio, TX) data center. Here’s its uptime report from Pingdom.com for March 2012:

image


Following is detailed Pingdom response time data for the month of March 2012:

image


This is the tenth uptime report for the two-Web role version of the sample project. Reports will continue on a monthly basis.

Month Year Uptime Downtime Outages Response Time
March 2012 99.96 00:20:00 1 767 ms
February 2012 99.92% 00:35:00 2 729 ms
January 2012 100.00% 00:00:00 0 773 ms
December 2011 100.00% 00:00:00 0 765 ms
November 2011 99.99% 00:05:00 1 708 ms
October 2011 99.99% 00:04:59 1 720 ms
September 2011 99.99% 00:05:00 1 743 ms
August 2011 99.98% 00:09:57 2 687 ms
July 2011 100.00% 00:00:00 0 643 ms
June 2011 100.00% 00:00:00 0 696 ms

The Azure Table Services Sample Project

See my Republished My Live Azure Table Storage Paging Demo App with Two Small Instances and Connect, RDP post of 5/9/2011 for more details of the Windows Azure test harness instance.

image_thumb2_thumb_thumb1_thumb_thum

imageI believe this project is the oldest continuously running Windows Azure application. I first deployed it in November 2008 when I was writing Cloud Computing with the Windows Azure Platform for Wiley/WROX, which was the first book published about Windows Azure.

The application runs the default set of Windows Azure Diagnostics. About 5 GB of Event Counter data provide the source data for my Generating Big Data for Use with SQL Azure Federations and Apache Hadoop on Windows Azure Clusters post of 1/8/2012.

For more details about the Table Services Sample project or to download its source code, visit its Microsoft Pinpoint entry. Following are Pinpoint listings for three other related OakLeaf sample projects, two of which are live in the South Central US data center:


Sunday, March 04, 2012

Windows Azure Compute Availability Logs: North and South Central US Data Centers, 2/29 and 3/1/2012

Following is a transcript of the logs for the Windows Azure Compute service disruption on 2/29 and 3/1/2012 for Microsoft’s North Central US (Chicago) and South Central US (San Antonio) data centers in chronological order:

image[Windows Azure Compute] [North Central US] [Yellow] Windows Azure Compute Availability
  • Feb 29 2012 10:55AM We are experiencing an issue with Windows Azure Compute in the North Central US sub-region. Incoming traffic may not go through for a subset of hosted services in this sub-region. Deployed applications will continue to run. There is no impact to storage accounts either. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 12:30PM We are still troubleshooting this issue and capturing all the data that will allow us to resolve it. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 1:45PM We are executing restoration steps to mitigate the issue. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 2:30PM We have determined that about 6.7% of hosted services in this sub-region are impacted by this issue. The restoration steps to mitigate the issue are underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 3:30PM The restoration steps to mitigate the issue are underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 4:30PM The restoration steps to mitigate the issue are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 5:30PM The restoration steps to mitigate the issue are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 6:30PM The restoration steps to mitigate the issue are still underway. This incident impacts Access Control 2.0, Marketplace, Service Bus and the Access Control & Caching Portal in the same regions where Windows Azure Compute is impacted. As a result affected customers may experience a loss of application functionality. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 7:30PM We are actively recovering Windows Azure hosted services in this sub-region. More and more customers applications should be back up-and-running even if service management functionality is not yet restored. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 8:30PM We have recovered over half of the Windows Azure hosted services that were impacted. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 9:30PM Recovery efforts are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 10:30PM Recovery efforts are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 11:30PM Recovery efforts are still underway, we are 70% through the recovery process and we restored full service management functionality for more customers in this region. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 1:00AM Recovery efforts are still underway. The majority of Windows Azure customers and services have been restored. However, a few customers and services remain affected and we are working aggressively to restore full functionality. We restored full service management functionality for most customers in this region. We have published a recap of the incident since it started on the Windows Azure team blog (http://blogs.msdn.com/b/windowsazure/archive/2012/03/01/windows-azure-service-disruption-update.aspx). Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 3:00AM We are working on stabilizing the Windows Azure Platform as well as following-up with all customers who were impacted by this incident. The recovery process continues. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 4:30AM Recovery efforts are still underway, we are 85% through the recovery process in terms of impacted hosted services. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 7:30AM Our recovery efforts to restore compute service to impacted customers in this sub-region are complete. A small number of customers in this sub-region may face long delays during service management operations. We request any customers experiencing compute or service management issues in this sub-region to reach out to us through the support channel described on this site: (http://www.windowsazure.com/en-us/support/contact). We apologize for any inconvenience this incident causes our customers.
  • Mar 1 2012 10:15AM We have confirmed that full functionality is restored in the North Central US sub-region. We apologize for any inconvenience this incident caused our customers.


image[Windows Azure Compute] [South Central US] [Yellow] Windows Azure Compute Availability
  • Feb 29 2012 10:55AM We are experiencing an issue with Windows Azure Compute in the South Central US sub-region. Incoming traffic may not go through for a subset of hosted services in this sub-region. Deployed applications will continue to run. There is no impact to storage accounts either. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 12:30PM We are still troubleshooting this issue and capturing all the data that will allow us to resolve it. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 1:30PM We are still troubleshooting this issue, and verifying the most probable cause. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 2:30PM We have determined that about 28% of hosted services in this sub-region are impacted by this issue. The restoration steps to mitigate the issue are underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 3:30PM The restoration steps to mitigate the issue are underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 4:30PM The restoration steps to mitigate the issue are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 5:30PM The restoration steps to mitigate the issue are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 6:30PM The restoration steps to mitigate the issue are still underway. This incident impacts Access Control 2.0, Marketplace, Service Bus and the Access Control & Caching Portal in the same regions where Windows Azure Compute is impacted. As a result affected customers may experience a loss of application functionality. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 7:30PM We are actively recovering Windows Azure hosted services in this sub-region. More and more customers applications should be back up-and-running even if service management functionality is not yet restored. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 8:30PM We have recovered over half of the Windows Azure hosted services that were impacted. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 9:30PM Recovery efforts are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 10:30PM Recovery efforts are still underway. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Feb 29 2012 11:30PM Recovery efforts are still underway, we are 70% through the recovery process and we restored full service management functionality for more customers in this region. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 1:00AM Recovery efforts are still underway. The majority of Windows Azure customers and services have been restored. However, a few customers and services remain affected and we are working aggressively to restore full functionality. We restored full service management functionality for all customers in this region. We have published a recap of the incident since it started on the Windows Azure team blog (http://blogs.msdn.com/b/windowsazure/archive/2012/03/01/windows-azure-service-disruption-update.aspx). Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 3:00AM We are working on stabilizing the Windows Azure Platform as well as following-up with all customers who were impacted by this incident. The recovery process continues. We are also focusing on restoring full service management functionality in this sub-region. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 4:30AM Recovery efforts are still underway, we are 85% through the recovery process in terms of impacted hosted services. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
  • Mar 1 2012 7:30AM Our recovery efforts to restore compute service to impacted customers in this sub-region are complete. A small number of customers in this sub-region may face long delays during service management operations. We request any customers experiencing compute or service management issues in this sub-region to reach out to us through the support channel described on this site: (http://www.windowsazure.com/en-us/support/contact). We apologize for any inconvenience this incident causes our customers.
  • Mar 1 2012 4:57PM We have confirmed that full functionality is restored in the South Central US sub-region. We apologize for any inconvenience this incident caused our customers.

OakLeaf Systems’ live demonstration Cloud Apps are hosted in the South Central US data center and had a total of 35 minutes of downtime. See Uptime Report for my Live OakLeaf Systems Azure Table Services Sample Project: February 2012 post of 3/3/2012.


Wednesday, February 29, 2012

Microsoft’s Official Response to the Windows Azure Outage of 2/29/2012

Bill Liang, Corporate VP, Server and Cloud, added the following post to the Windows Azure blog on 2/29/2012:

imageI lead the engineering organization responsible for the Windows Azure service and I want to update you on the service disruption we had over the past day. First let me apologize for any inconvenience this disruption has caused our customers. Our focus over the past day has been to resolve the Windows Azure Compute service disruption. As always we communicate the status of incidents through the Windows Azure Service Dashboard and update that status on an hourly basis or as the situation changes.

imageYesterday, February 28th, 2012 at 5:45 PM PST Windows Azure operations became aware of an issue impacting the compute service in a number of regions. The issue was quickly triaged and it was determined to be caused by a software bug. While final root cause analysis is in progress, this issue appears to be due to a time calculation that was incorrect for the leap year. Once we discovered the issue we immediately took steps to protect customer services that were already up and running, and began creating a fix for the issue. The fix was successfully deployed to most of the Windows Azure sub-regions and we restored Windows Azure service availability to the majority of our customers and services by 2:57AM PST, Feb 29th.

However, some sub-regions and customers are still experiencing issues and as a result of these issues they may be experiencing a loss of application functionality. We are actively working to address these remaining issues. Customers should refer to the Windows Azure Service Dashboard for latest status. Windows Azure Storage was not impacted by this issue.

We will post an update on this situation, including details on the root cause analysis at the end of this incident. However, our current priority is to restore functionality for all of our customers, sub-regions and services.
We sincerely apologize for any inconvenience this has caused.

imageAccording to Pingdom, my OakLeaf Systems Azure Table Services Sample Project (Tools v1.4 with Azure Storage Analytics) was down for five minutes or less. The next OakLeaf Uptime Report, expected to post on 3/3/2012, will provide confirmation of downltime during the period in question. My SQL Azure Reporting Systems Preview Demo service indicated no problems during intermittent tests on 2/29/2012.

Wednesday, April 21, 2010

Windows Azure Live DNS Brief Outage at All Data Centers on 4/21/2010 at ~ 2:30 PM PDT

I received the following alert from Pingdom on 4/21/2010:

PingdomAlert DOWN:
  Azure Tables (oakleaf.cloudapp.net) is down since 04/21/2010 01:48:21PM.

and from Mon.itor.us:

image

Following is a screen capture of the Azure service dashboard at about 3:00 PM PDT (click for full 1024px width version):

Notice that DNS is reported to have failed for all Data Centers, which would indicate that storage and compute replicas geolocated in multiple data centers would not have solved the problem.

Here’s the mouse-over message that appeared in the Status History section after the live DNS operation was reported restored (and confirmed by me for the OakLeaf test harness) at about 3:00 PM PDT:

image 

Pingdom reports the outage duration was ~40 minutes:

PingdomAlert UP:
  Azure Tables (oakleaf.cloudapp.net) is UP again at 04/21/2010 02:28:21PM after 40m of downtime.

The outage resulted in a few #FAIL tweets with the #Azure hashtag:

Here’s the mouse-over message for the AppFabric Service Bus problem in the South Central US data center:

image 

and the Project “Dallas” portal and content in the same data center:

image

I’ll update this post if the Windows Azure, Data Center team, or both provide an explanation for the outage.